Projects

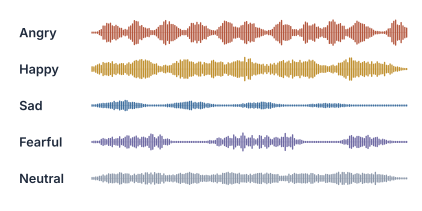
Illustrative speech waveforms for angry, happy, sad, fearful and neutral delivery

2024

Mood Monitoring with Speech Emotion Recognition

At Emobot, I led research on automatic speech emotion recognition — pushing accuracy significantly through synthetic data augmentation via emotion conversion, with direct impact on a real-time healthcare application.
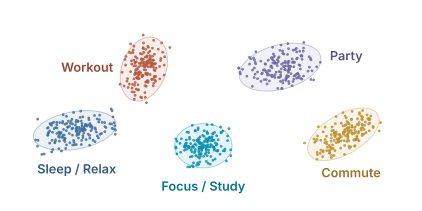
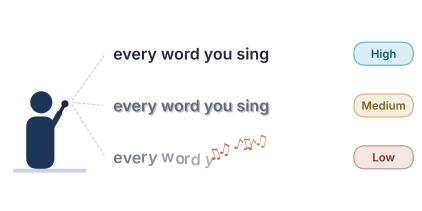
Illustration of music tracks grouped into listening-context clusters: Workout, Party, Sleep / Relax, Focus / Study and Commute

2022

Contextual Music Recommendation

My PhD project at Télécom Paris and Deezer, studying how listening context — activity, mood, device, time of day — shapes what music people want to hear, and building systems that learn to predict it automatically.

A singer sends the same lyric line three times: crisp next to High intelligibility, smudged next to Medium, and dissolving into music notes next to Low

2018

Singing Voice Intelligibility

For my M.Sc. at NUS, I studied what makes song lyrics easy or hard to understand, and built systems to measure it automatically — motivated by a real application: recommending music for language learning.

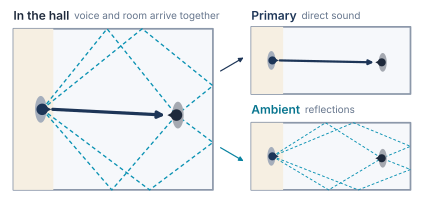
Top-down concert hall where a singer's direct sound and its wall reflections reach a listener, then shown separated into a primary (direct sound) layer and an ambient (reflections) layer

2016

Primary-Ambient Source Separation

My first research project, spanning my M.Sc. at Nile University and an internship at Sony Stuttgart. The goal: automatically separate the direct sound from the diffuse ambience in a stereo recording, to enable surround sound upmixing.